
Robodanesh
Document register
- Poster1 pagePublished
- Presentation videoYouTubePublished
- Bill of materialsNot shared
- Team description paper912 KBPublished
- Engineering journalNot shared
- Source codeNot shared
Sharing each document is the team's decision. “Not shared” means this team chose not to publish it, or did not submit one — not that it is missing from the archive.
In their words
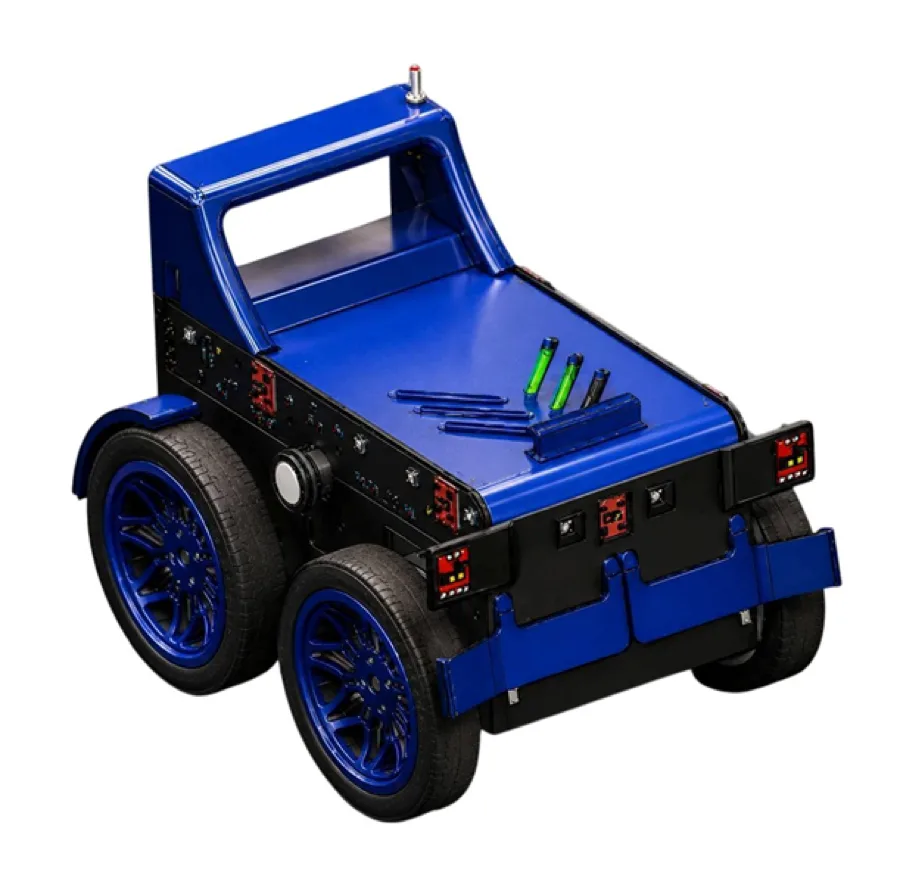
This paper presents the design and development of an autonomous rescue robot by Team RoboDanesh for the RoboCup Rescue Maze competition. The robot is designed to operate reliably in complex and dynamic environments, simulating the challenges of real-world disaster scenarios. Its main capabilities include autonomous navigation, path planning, obstacle and wall detection, ramp traversal, victim identification, and rescue kit deployment.
The robot is built on an integrated mechanical, electronic, and software architecture. The mechanical design emphasizes stability, durability, and modularity, allowing reliable movement over uneven surfaces. The electronics are centered around a main controller supported by custom circuit boards, enabling efficient sensor integration, motor control, and communication. Environmental perception is achieved using VL53L1X distance sensors for walls and obstacles, Microswitches for physical contact, APDS-9960 and IR sensors for surface color recognition, and a CMPS14 digital compass for orientation. The software architecture combines structured navigation and decision-making algorithms with vision-based victim detection. Image processing is handled on a Raspberry Pi 5 using Python and established computer vision libraries. Particular focus was placed on integrating subsystems, validating performance through testing, and refining the robot iteratively. These design choices result in a stable, responsive, and adaptable robot capable of reliable performance in challenging rescue maze scenarios.
Poster
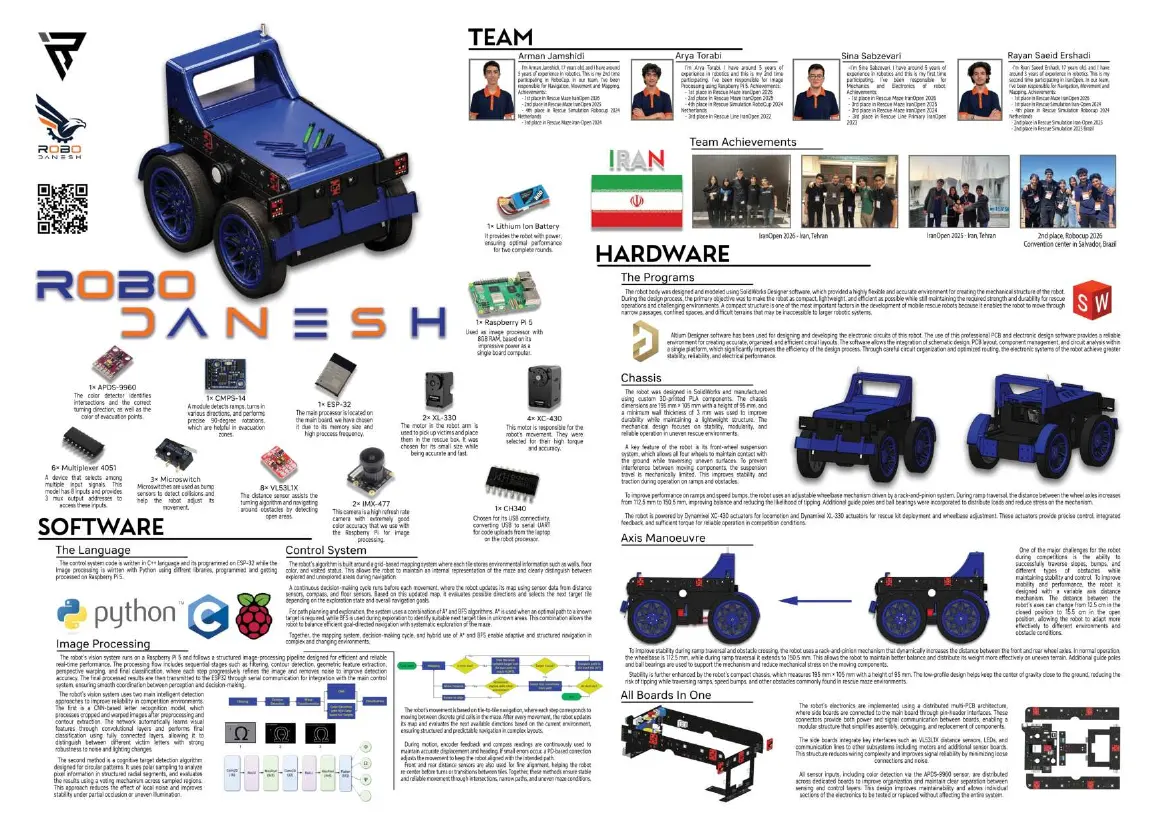
1 page, rendered as images so they load quickly. This document has no text layer — the words in it are part of the image.
Presentation video
Hosted on YouTube. The player loads only when you press play.
Team description paper
Shown as the original PDF, because this one is smaller that way and its text stays selectable and searchable.